Most businesses don't have a lead problem. They have a lead prioritisation problem: a sales team drowning in enquiries, half of which were never going to buy, while the two or three genuinely ready-to-buy prospects sit in the same inbox as everyone else, waiting their turn.
Lead scoring fixes that. It's the discipline of ranking every lead by how likely they are to actually become a paying customer, so your sales team knows exactly who to call first, who to nurture patiently, and who to stop chasing altogether. This guide covers what lead scoring actually involves, how to build a model that works for a UK business rather than a Silicon Valley enterprise, and the mistakes that quietly break most scoring systems within a few months of launch.
This sits alongside two questions most businesses ask around the same time: how to actually generate a healthier volume of leads in the first place, and how to make sure the ones already arriving are worth the sales team's attention. If lead volume itself is the bigger problem right now, our guide on how to generate qualified leads is the natural starting point before scoring becomes the priority.
Lead scoring is a system for assigning a numerical value to every lead in your pipeline, based on how well they match your ideal customer and how engaged they've been with your business. The higher the score, the more ready that lead is for a genuine sales conversation.
It sounds simple, and the underlying idea is. A lead who downloaded a pricing guide, visited your services page three times, and works at a company the right size for your offer clearly deserves a faster follow-up than someone who opened one email a month ago and hasn't been seen since.
What trips businesses up isn't the concept, it's the execution. A scoring model built once and never revisited drifts out of sync with reality within months. A model with no negative scoring lets students, competitors and dead-end enquiries sit at the same score as your best prospects. Both mistakes are common, and both are fixable once you understand what's actually going wrong.
Lead scoring isn't the same thing as lead qualification, though the two are closely related. Qualification is the judgement call a rep makes on a call. Scoring is what decides which leads get that call in the first place, and in what order. If you haven't already read it, our guide on how to qualify sales leads for higher conversion covers the conversation side of this once a lead has been scored and handed to sales.
Research into lead scoring adoption suggests that fewer than half of organisations actually run a formal scoring system, with the rest still qualifying leads manually, one gut-feel judgement at a time. That gap matters more than it looks, because manual qualification scales badly the moment lead volume goes up.
The businesses that do use scoring consistently report meaningfully better returns than those that don't, roughly double in some of the studies looking at this. That's not a coincidence. A rep working a properly scored list spends their limited time on the leads most likely to close, rather than working every enquiry in the order it arrived.
The waste without scoring is real and well documented. Research repeatedly finds that only around a quarter of leads passed to sales teams are genuinely sales-ready, meaning the other three-quarters are consuming rep time that could have gone toward the leads actually worth pursuing. That's the core economic case for building a scoring model in the first place.
Most UK small and medium businesses that skip lead scoring do so for one of two reasons: they assume it needs an expensive enterprise CRM, or they tried a spreadsheet once, found it out of date within a month, and gave up. Neither reason holds up once you see how a scoring model is actually built, which is what the rest of this guide covers.
Poor lead quality compounds the problem further. A scoring model built on top of genuinely weak leads, the wrong audience, badly targeted campaigns, low-intent traffic, will always struggle, however carefully it's designed. If lead quality itself looks shaky before you even get to scoring, our guide on how to improve lead quality is worth tackling first.
Lead scoring isn't about generating more leads. It's about making sure the leads you already have get worked in the right order, because most businesses without a scoring system are quietly wasting sales time on leads that were never going to buy.
Every workable lead scoring model rests on two separate types of signal, scored independently and then combined. Businesses that only track one of the two consistently end up chasing the wrong leads, just in a different way each time.
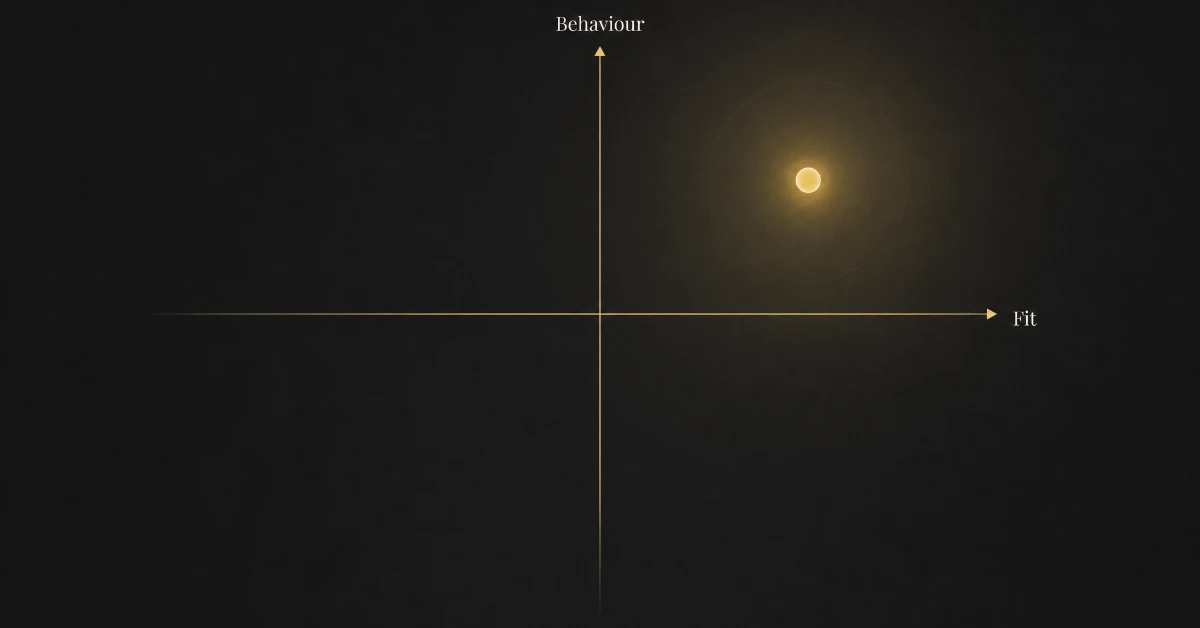
Fit scoring looks at who the lead is, independent of anything they've done. For a B2B business this usually means company size, industry, job title or seniority, and geography. For a consumer business it's closer to budget, location and the specific need they've described.
A lead can be a perfect fit and still be months away from buying, and a lead can be actively browsing your pricing page while being a terrible fit for what you actually sell. Fit alone never tells you when to call. It only tells you whether the call is worth having at all.
Behavioural scoring tracks engagement: pages visited, emails opened and clicked, content downloaded, webinars attended, pricing pages viewed, and how recently any of that happened. This is the half of the model that changes daily, and the half most spreadsheet-based systems fail to keep current.
Recency matters as much as volume here. A lead who visited your pricing page ten times last year but nothing since is a colder prospect than one who visited it twice this week, even though the raw visit count favours the first. Most basic scoring models miss this entirely.
High fit and high behaviour together is the genuine hot lead: the right company, the right person, and clear signs they're actively evaluating a purchase. That combination is what separates real lead scoring from either a static contact database or a raw engagement leaderboard, neither of which tells the full story alone.
A useful way to picture this in practice: a high-fit, low-behaviour lead is worth a patient nurture sequence rather than an immediate call, while a low-fit, high-behaviour lead is often a student, a competitor doing research, or a job seeker rather than a genuine prospect. Scoring both axes separately keeps you from mistreating either.
You don't need an enterprise marketing platform to run a real scoring model. A CRM with custom fields, or even a well-maintained spreadsheet for a smaller pipeline, is enough to start. What matters is following the process properly rather than the tool you use to run it.
Step six is the one businesses skip most often, and it's the one that determines whether the whole model is worth trusting. A scoring threshold that was never tested against real closed deals is just a guess dressed up as a system, however confident the spreadsheet looks.
A lead scoring model built from your own best customers, with fit and behaviour scored separately and tested against real closed deals, beats any generic template. The process matters more than the tool running it.
Positive scoring alone eventually breaks, because a scoring system that only ever adds points has nowhere to send a lead that's clearly gone cold or was never a real prospect in the first place. Negative scoring is what keeps the top of your list genuinely trustworthy.
The most common negative signals are worth building into every model from the start: a personal email address on a B2B enquiry, a job title that's clearly not a decision maker, a company size well below or above your realistic serving range, unsubscribing from emails, or a long stretch of complete inactivity after early engagement.
Competitor and job-seeker traffic deserves its own negative rule in most B2B models. Someone browsing your careers page or downloading a document titled with your own company name in the search term is very rarely a buyer, whatever their behavioural score suggests on paper.
A well-built negative scoring layer also protects your sales team's trust in the system. The fastest way to get reps to quietly ignore a lead scoring model is to let it keep handing them dead-end leads with impressive-looking scores. One or two bad handoffs and most reps go back to working the list by gut feel.
A raw numerical score is useful for sorting a list, but it's not how most sales teams actually think about a lead. Grading converts the number into a simple tier that tells a rep, at a glance, how to treat that lead without doing mental arithmetic first.
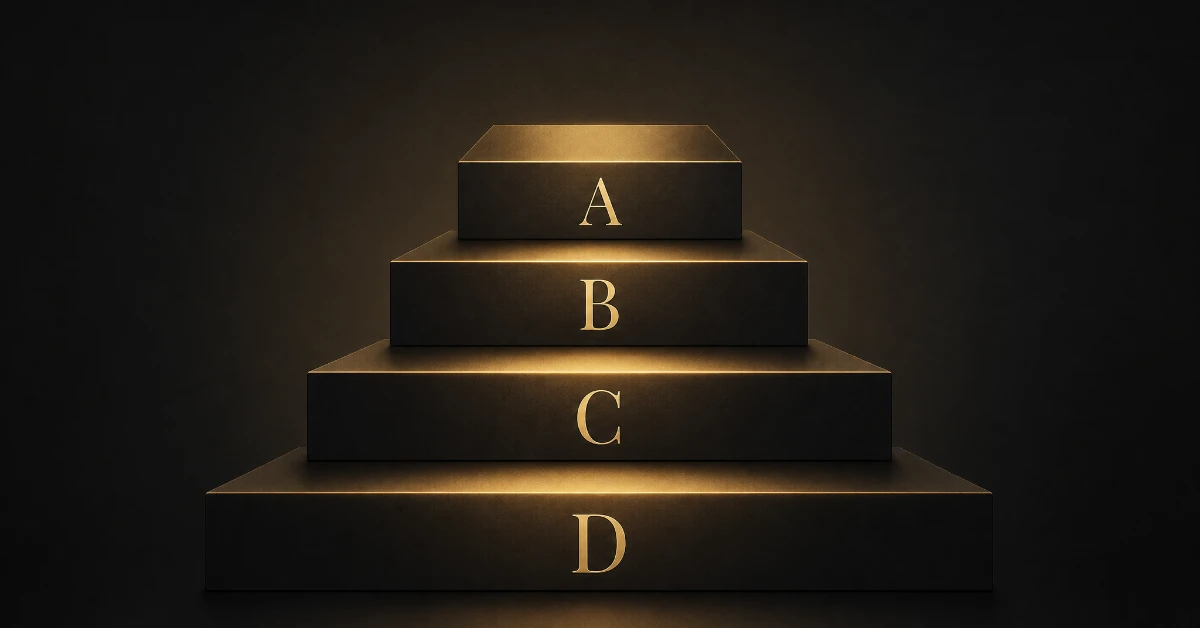
Most models settle on four tiers, often labelled A to D or hot, warm, cool and cold. What matters isn't the label, it's that every tier comes with a clear, agreed action, so the score actually changes what happens next rather than just sitting in a column nobody checks.
| Tier | What it represents | Recommended action |
|---|---|---|
| A (Hot) | Strong fit, strong recent engagement | Call within the hour, treat as a live opportunity |
| B (Warm) | Strong fit, moderate or ageing engagement | Personal follow-up within a day, not an automated sequence |
| C (Cool) | Moderate fit or fit unconfirmed, some engagement | Enrol in nurturing, re-score after further activity |
| D (Cold) | Poor fit or negative signals present | Low-touch nurture only, exclude from active sales queue |
The tier boundaries should come from the same test you ran in step six of building the model: look at where your actual closed deals fell on the score scale, and set the A/B boundary just below the lowest score that historically closed, rather than picking a round number that feels right.
A score only becomes useful once it's translated into a tier with a clear action attached. Four simple tiers, each with its own agreed response, do more for sales productivity than a precise but unexplained number ever will.
A lead's source is one of the strongest predictors of how quickly they'll buy, yet most scoring models treat every channel identically. Building channel context into your model, even as a simple adjustment, makes the score considerably more accurate without much extra work.
A lead from Google Ads has already searched for a solution, which usually means genuine, existing intent. These leads typically deserve a modest fit-score boost, since simply arriving via a commercial-intent keyword is itself a weak positive signal worth a few points.
Organic leads split into two very different groups: those landing on a commercial page like a services or pricing page, and those arriving on an educational blog post. The former deserves a real fit boost; the latter is often still in research mode and shouldn't be scored the same way.
A referral from an existing customer or partner typically converts at a far higher rate than any paid channel, because someone the lead already trusts has effectively pre-qualified them. Most models under-weight referrals simply because there's no click or download to score, so build in a manual fit boost for this source.
A lead magnet download is a weak behavioural signal on its own, and treating it as a strong one is a common cause of an over-inflated score. Weight it modestly, and let a second, more commercial action, such as visiting a pricing page afterwards, be what actually pushes the score into hot territory.
A lead who replied positively to a cold outbound message has shown genuine intent despite no prior warmth, and deserves more credit than the same behaviour from an inbound lead who was already primed to respond. Context always matters more than the raw action recorded.
A perfectly scored lead still goes cold if nobody calls them quickly. Speed to lead, the time between a lead arriving and a human making contact, is one of the most consistently under-appreciated factors in whether a scoring system actually pays off.
Studies of company response times have repeatedly found that businesses are, on average, remarkably slow, with some putting the typical B2B first-response time at well over 40 hours, and a large share of companies taking five days or longer. Meanwhile, research on lead response consistently shows that contacting a lead within the first five minutes makes you dramatically more likely both to reach them at all and to actually qualify them, compared with waiting even half an hour.
This is exactly why grading leads into tiers with a defined action (Section 6) matters so much in practice. An A-tier lead sitting unread in a shared inbox for two days has effectively been demoted to a D-tier lead by the time anyone picks up the phone, no matter how high the score originally said it was.
Route hot leads to an alert that actually interrupts someone's day, not just an email that sits in a queue with fifty others. A simple Slack or SMS notification the moment a lead crosses the A-tier threshold does more for close rates than almost any other single change most businesses can make.
A perfect scoring model is worthless if the hottest leads still sit unread for two days. Speed to lead and lead scoring have to be built together, because a great score with a slow follow-up is functionally the same as no score at all.
There isn't a single right tool for lead scoring, and the right choice depends heavily on lead volume, budget and how much of this you want to manage by hand versus let a system handle automatically.
Perfectly workable for a low volume of leads, a spreadsheet forces genuine discipline about what you're actually scoring and why. Its weakness is upkeep: behavioural data has to be manually updated, which is exactly the step that quietly stops happening once volume creeps up.
Most mid-tier CRMs, including HubSpot and Salesforce, include rule-based scoring that automatically updates as leads take defined actions. This is the sweet spot for most growing UK businesses: automated enough to stay current, simple enough not to need a data science team to maintain it.
Predictive models look at historical closed-won and closed-lost data and identify the actual patterns that preceded a sale, rather than relying on a human's best guess at which criteria matter. Research on AI-driven scoring has found it can meaningfully improve accuracy over basic rule-based models, but it needs a real volume of historical deal data to learn from, and isn't worth the added complexity below a certain lead volume. This is closely related to, but distinct from, AI-driven lead nurturing itself, and our breakdown of what AI lead nurturing actually costs UK businesses is a useful companion read if you're weighing up the investment in either.
| Approach | Best suited to | Main limitation |
|---|---|---|
| Manual spreadsheet | Under roughly 50 new leads a month | Upkeep fails quietly as volume grows |
| Native CRM rules | Roughly 50-500 new leads a month | Rules need periodic manual re-tuning |
| AI-driven predictive | 500+ leads a month with real deal history | Needs volume and clean data to learn from |
Whichever tier you're in, the model is only as good as the follow-up process wrapped around it. A predictive AI score with no fast human or automated response behind it solves nothing that a spreadsheet couldn't. If your business is leaning toward automated follow-up alongside scoring, our guide on what AI lead nurturing actually is covers how the two work together.
Most of these mistakes share a root cause: treating lead scoring as a one-off project rather than an ongoing process. The businesses getting real value from scoring are the ones re-checking it against actual closed deals every quarter, not the ones who built a clever spreadsheet once and forgot about it.
Nearly every broken lead scoring model traces back to the same root cause: it was built once and never checked again. Treat scoring as a living process, reviewed against real closed deals, not a spreadsheet you finish and forget.
A UK-based professional services firm sells a service best suited to companies with 20-200 staff. A lead arrives: an operations manager at a 60-person logistics firm, who found the site through an organic search for the firm's core service.
On fit, the company size sits squarely in the target range, worth a strong positive score. The job title is a genuine influencer, though not the final decision maker, worth a moderate rather than maximum score. The industry is one the firm serves often, adding another small positive.
On behaviour, arriving via a commercial-intent organic search earns a modest boost. Over the following week the lead visits the pricing page twice and downloads a comparison guide, both strong positive signals, and opens two follow-up emails without unsubscribing, a smaller additional positive.
Combined, this lead clears the firm's A-tier threshold: strong fit, clear and recent commercial-intent behaviour, no negative signals present. Under the tier table from Section 6, that means a call within the hour rather than sitting in a general follow-up queue behind lower-scoring enquiries.
Contrast that with a second lead the same week: a marketing intern at a 3,000-person enterprise, who downloaded the same comparison guide out of general curiosity and hasn't visited the site since. Same behavioural action, completely different fit, and a B or C-tier score rather than A once both dimensions are scored properly.
A scoring model isn't something you set up once and trust indefinitely. A handful of straightforward metrics tell you fairly quickly whether it's genuinely improving how sales spends its time, or just adding a number nobody actually uses.
Track your MQL-to-SQL conversion rate: the share of scored, marketing-qualified leads that sales actually accepts as genuinely sales-ready. Typical B2B conversion here tends to sit in a fairly modest range, with well-tuned scoring models, particularly ones using solid behavioural signals, pushing meaningfully higher over time as the weightings improve. Watching this number alongside your actual customer acquisition cost gives a fuller picture of whether the whole pipeline, not just the scoring layer, is genuinely efficient; our guide on calculating customer acquisition cost covers that side of the equation in full.
Track your sales acceptance rate directly with the reps working the list. If reps are routinely rejecting A-tier leads as not genuinely ready, that's not a sales problem, it's a scoring problem, and the weightings need revisiting before you touch anything else in the funnel.
Track win rate by tier. If your A and D tiers are closing at similar rates, the model isn't actually separating good leads from poor ones, whatever the scores on paper suggest, and it's worth going back to step six of the build process and re-testing against real closed deals.
Finally, track average time-to-contact by tier. If your hottest leads aren't consistently getting the fastest response, the scoring work in Sections 3 to 6 of this guide is being undone entirely by the process gap covered in Section 8, and that gap is usually the cheaper, faster thing to fix first.
A lead scoring model earns its keep only if it's measured. Track MQL-to-SQL conversion, sales acceptance, win rate by tier and time-to-contact, and let those four numbers, not a gut feeling, tell you whether the model needs adjusting.
There's no universal number, since every model uses different point values. The right threshold is whichever score your actual historical closed deals cleared, which is why testing the model against real closed business (Section 4, step six) matters more than picking a round number that feels right.
No. A small team benefits arguably more, since every hour spent on a poorly matched lead is a much larger share of total capacity. A simple spreadsheet model, reviewed monthly, is enough for most small UK businesses to start seeing the benefit.
Monthly for the first quarter after launch, then quarterly once the weightings have settled and the tier boundaries are tracking real closed deals reliably. A model reviewed only once a year will drift noticeably out of step with your actual customer profile.
Yes, for lower lead volumes. A well-maintained spreadsheet with clear fit and behaviour columns, updated consistently, works fine below roughly 50 new leads a month. Beyond that, the manual upkeep becomes the model's weak point, and a CRM with native scoring rules is worth the move.
No, the two work together rather than as alternatives. Scoring tells you which leads deserve an immediate call versus a patient nurture sequence; nurturing is what keeps the lower-scoring leads warm until their behaviour and fit eventually earn them a higher tier.
Scoring produces the underlying number from fit and behaviour criteria; grading is the step that converts that number into a simple tier, such as A to D, with a clear agreed action attached. Most working models use both together, as covered in Section 6.
Lead scoring isn't a nice-to-have for businesses with more leads than they know what to do with. It's a practical fix for the much more common problem: a sales team spending real hours on leads that were never going to close, while the genuinely ready buyers wait in the same queue.
Start with your own best customers, score fit and behaviour separately, build in negative scoring from day one, and test the whole thing against real closed deals before trusting it. Everything else in this guide, from channel context to speed to lead, is refinement on top of that foundation.
If your business is generating a reasonable volume of leads but still isn't sure which ones are worth chasing first, that's exactly the gap a proper scoring model closes. Understanding your true cost per lead is the natural next step alongside it, and our guide on what a good cost per lead actually looks like is a useful place to continue.
Lead scoring doesn't create better leads. It makes sure the good leads you already have get found, and called, before they go cold waiting behind everyone else.